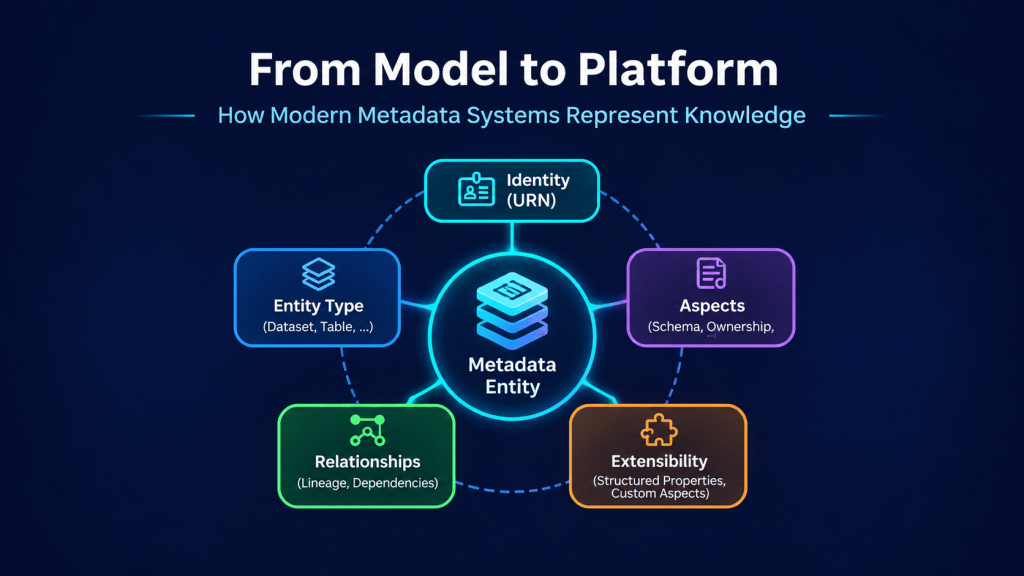
From Model to Platform: How Modern Metadata Systems Represent Knowledge
Understanding Metadata Systems
This article is part of my Understanding Metadata Systems series, where I explore metadata platforms from first principles—from why metadata exists to how these systems are modelled, implemented and operated.
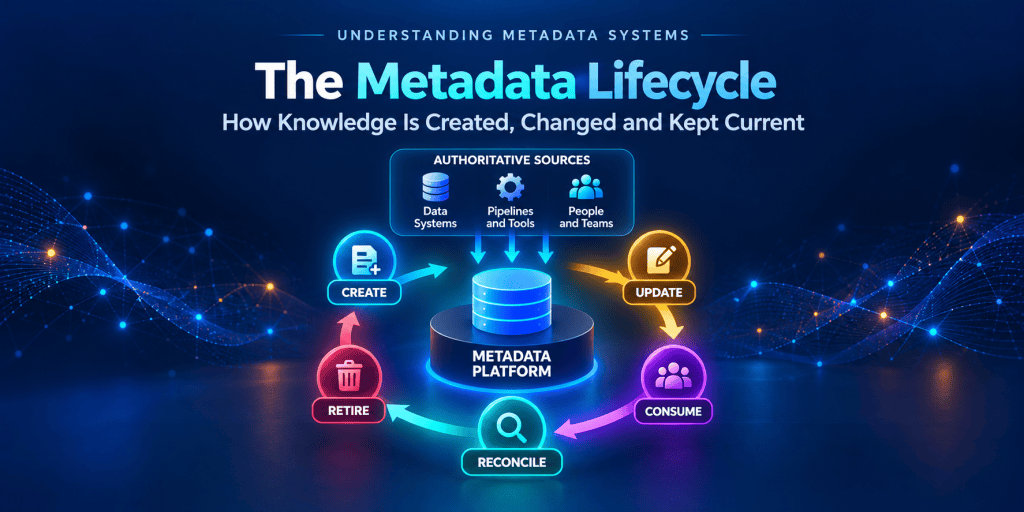
Previous: The Metadata Lifecycle: How Knowledge Is Created, Changed and Kept Current
Throughout this series, we have deliberately avoided starting with a particular metadata product.
Instead, we started with the problems.
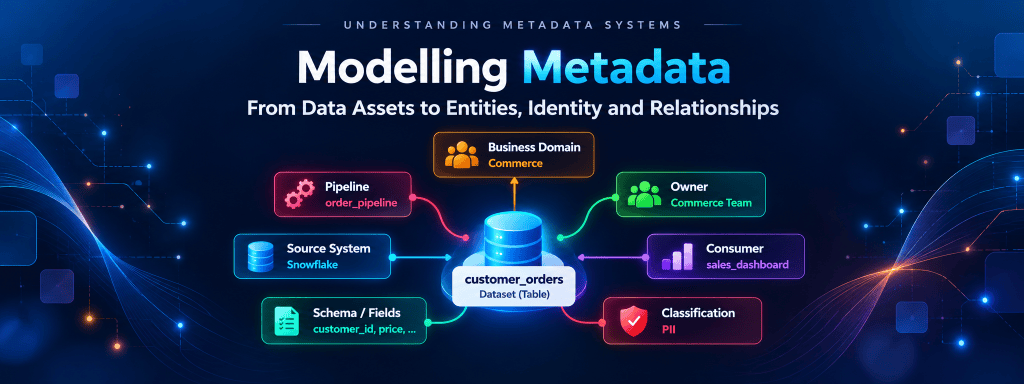
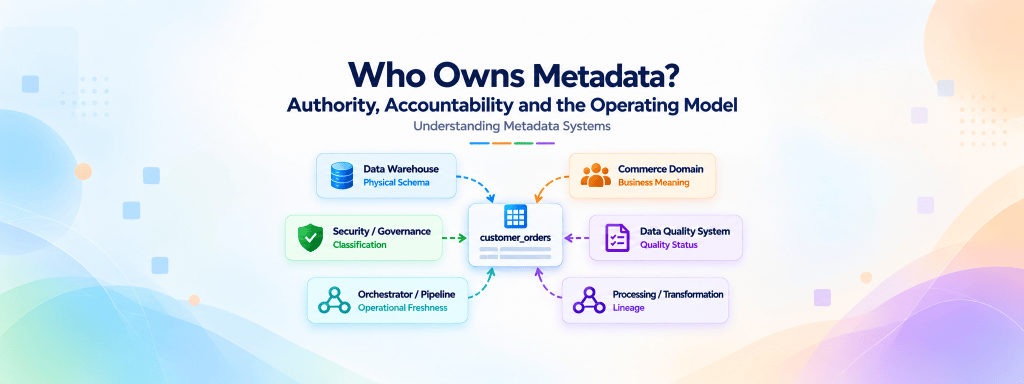
We explored why metadata is necessary, why distributed knowledge creates the need for shared metadata capabilities, how ownership and authority remain distributed, and how metadata can be represented through entities, identities, types, metadata components and relationships.
In the previous article, we also explored how that knowledge changes over time and why metadata platforms need mechanisms to acquire, update and reconcile it.
We now have a reasonable understanding of what a metadata platform needs to accomplish.
But how do real metadata platforms implement these concepts?
There are several metadata platforms available today, including DataHub, OpenMetadata and Google Cloud Knowledge Catalog.
In this article, I will primarily use DataHub as an implementation example because of my hands-on experience with the product across client projects, including its architecture, deployment, integration and operations. Where relevant, I will also refer to OpenMetadata and Google Cloud Knowledge Catalog to understand how similar concepts are implemented across different platforms.
The objective is not to compare products or determine which one is better, but to understand how the architectural concepts we derived earlier translate into actual platform implementations.
Before Looking at Products, Recall Our Generic Model
In Blog 5, we derived a simple metadata information model by asking six questions.
| Question | Concept |
|---|---|
| What are we representing? | Entity |
| Which exact one? | Identity |
| What kind of thing is it? | Type |
| What do we know about it? | Metadata components |
| What additional knowledge do we need? | Extensibility |
| How is it connected to other things? | Relationships |
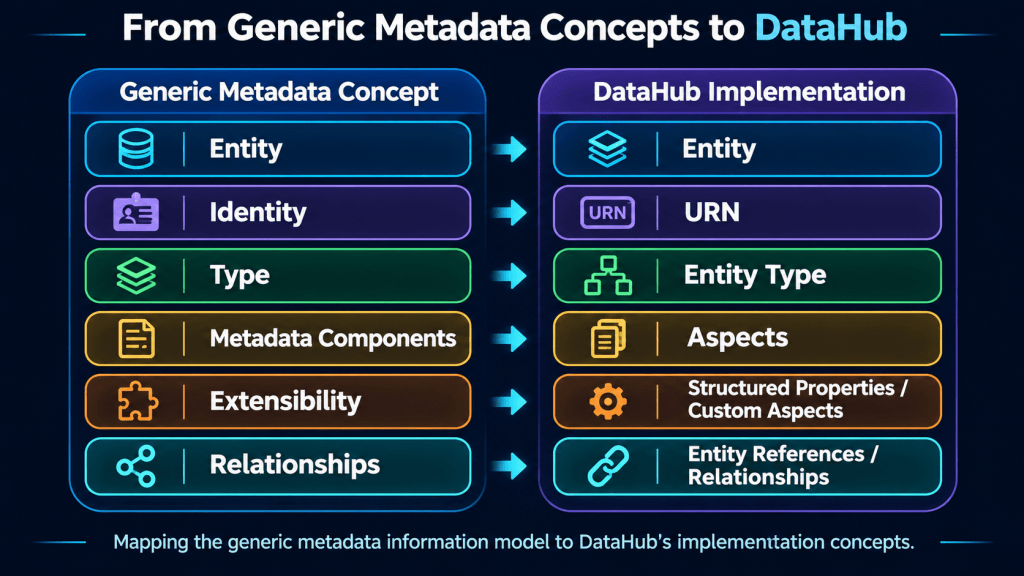
We also established an important principle:
Before deciding how metadata should be stored, we first need to decide what the metadata system needs to know.
Now we can examine how DataHub represents these concepts.
DataHub: Representing Knowledge Through Entities
DataHub is an open-source metadata platform designed to support metadata discovery, management and governance across a data ecosystem.
Its metadata model is built around several important concepts:
Entities, URNs, Entity Types, Aspects and Relationships.
Let us return to our familiar example:
customer_orders
Suppose this is a Snowflake table containing customer order information.
From our generic model, we already know that the metadata platform needs to represent this dataset as an identifiable entity.
In DataHub, a dataset is represented using the Dataset entity type.
But simply calling it customer_orders is not enough. We need to distinguish it from another table with the same name in a different database, environment or platform.
This brings us to identity.
URNs: Establishing Entity Identity
DataHub uses Uniform Resource Names (URNs) to identify metadata entities.
For example, a dataset URN might look like this:
urn:li:dataset:(urn:li:dataPlatform:snowflake,PRODUCTION.COMMERCE.CUSTOMER_ORDERS,PROD)
This identifies a particular dataset using information that includes its data platform, dataset name and environment.
The exact naming conventions depend on the platform and ingestion configuration.
The important point is that the URN provides the identity used to reference that entity within DataHub.
Consider two datasets:
PRODUCTION.COMMERCE.CUSTOMER_ORDERSTEST.COMMERCE.CUSTOMER_ORDERS
They may have similar human-readable names, but they represent different objects.
Their DataHub identities need to distinguish them.
This directly maps to the identity problem we discussed in Blog 5.
A metadata platform must distinguish an entity’s identity from its human-readable name and from the metadata describing it.
There is another subtle point.
A URN is a logical identifier, not a guarantee that identity will remain unchanged under every source-system operation.
For example, renaming an underlying object may change the identifier produced by an ingestion integration.
How a platform handles such changes is part of its metadata lifecycle and integration design.
Aspects: Separating Different Kinds of Knowledge
Identifying an entity is only the beginning.
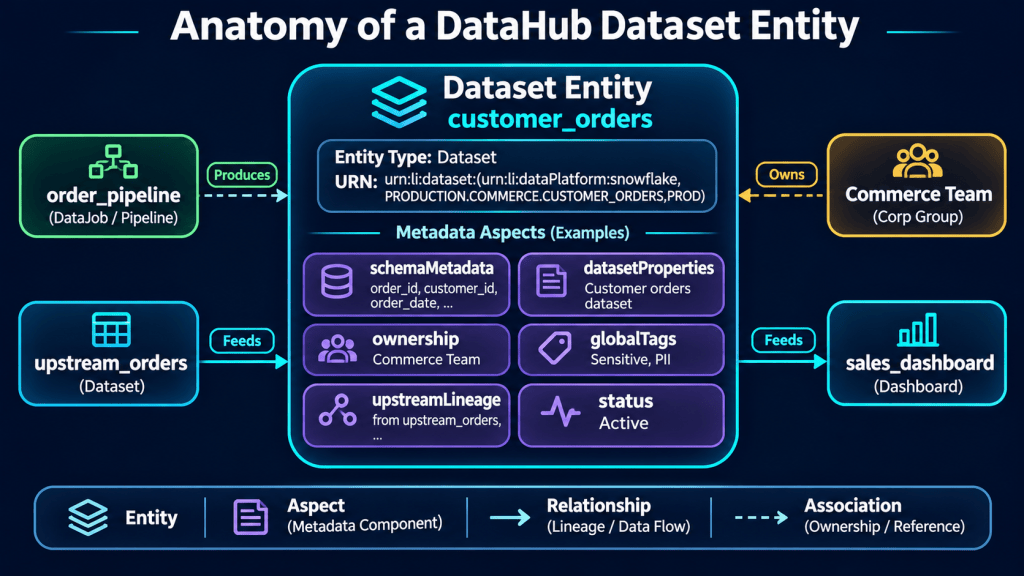
For our customer_orders dataset, we may need to represent:
- Schema
- Description
- Ownership
- Classification
- Lineage
- Status
- Operational properties
All these describe the same dataset, but they represent different kinds of knowledge.
DataHub addresses this using Aspects.
An aspect is a structured unit of metadata associated with an entity.
For example, a Dataset entity may have aspects such as:
| DataHub Aspect | What It Represents |
|---|---|
schemaMetadata | Schema fields, types and related schema information |
datasetProperties | Dataset description and other properties |
ownership | Ownership associations |
globalTags | Tags associated with the entity |
upstreamLineage | Upstream lineage information |
status | Entity status, including removal state |
structuredProperties | Assigned structured property values |
Conceptually:
Dataset Entitycustomer_orders │ ├── schemaMetadata ├── datasetProperties ├── ownership ├── globalTags ├── upstreamLineage ├── status └── structuredProperties
This is a useful architectural design.
Instead of representing every piece of metadata as one undifferentiated object, DataHub separates different categories of knowledge into defined structures.
For example, the warehouse may provide schema metadata, while a domain team contributes business descriptions and ownership information.
These components can have different producers and update patterns.
However, separating metadata into aspects does not automatically solve ownership conflicts.
The operating model still needs to establish which systems or teams are authoritative for particular information.
This connects directly to Blog 4.
A metadata model can separate knowledge into components, but the operating model must still determine who is authoritative for each component.
Relationships: Connecting Entities
Metadata becomes considerably more useful when entities can be related to one another.
Consider:
order_pipeline │ │ produces ▼customer_orders │ │ consumed by ▼sales_dashboard
In DataHub, relationships between entities can be represented through references contained in metadata aspects.
For example,
- The
upstreamLineageaspect can reference upstream datasets. - Ownership metadata can reference users or groups.
- Container associations can connect datasets to their organizational or technical containers.
These relationships allow DataHub to support capabilities such as lineage exploration, ownership navigation and impact analysis.
An important distinction is that relationships are not necessarily stored as independent graph records in a graph database.
DataHub’s metadata model expresses relationships through entity references and associated metadata structures.
The platform can then derive and expose connected views of the metadata ecosystem.
This reinforces the principle we established earlier:
A graph-shaped information model does not automatically require a graph database.
How relationships are persisted, indexed and queried is a separate architectural decision.
We will explore that in the next article.
Extensibility: When the Standard Model Is Not Enough
A generic metadata platform cannot anticipate every organization’s requirements.
Suppose we want to capture additional information about customer_orders:
Business Criticality: Tier 1Data Residency: EURegulatory Scope: GDPRReview Frequency: Quarterly
Some of this information may not fit naturally into the standard metadata fields provided by the platform.
DataHub supports extensibility through several mechanisms.
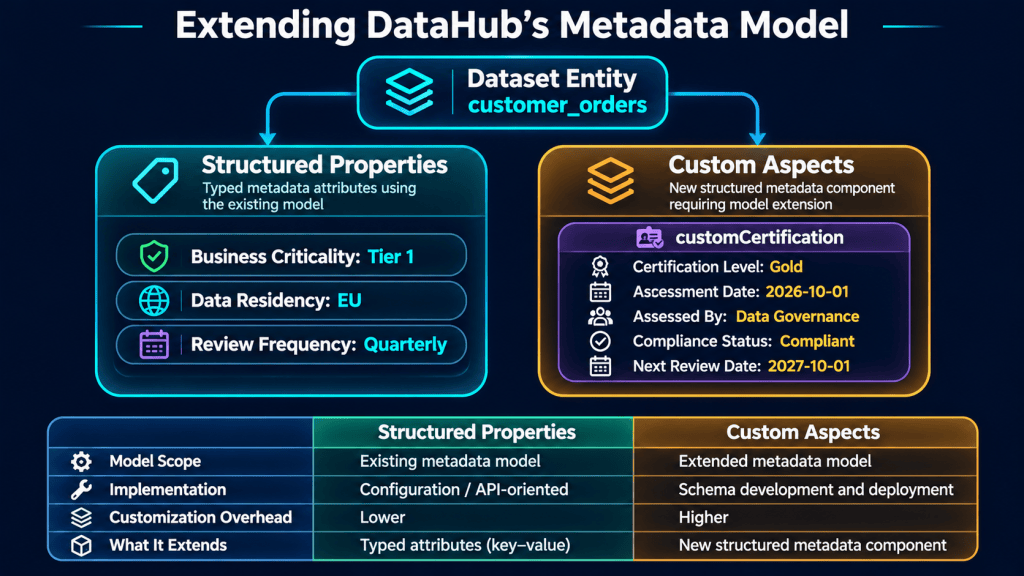
One important capability is Structured Properties.
Structured Properties allow organizations to define additional typed metadata attributes and associate values with supported entity types.
Conceptually, this involves two distinct things.
First, define the property.
For example:
Property:Business CriticalityValue Type:StringAllowed Values:Tier 1Tier 2Tier 3
Then assign a value to an entity.
Entity:customer_ordersStructured Property:Business Criticality = Tier 1
In DataHub’s model, the property definition and the property assignment are not the same thing.
A Structured Property definition is represented as its own metadata entity.
The values assigned to a supported target entity are represented through that entity’s structuredProperties aspect.
This distinction matters because a property definition may be reused across many entities.
For example, hundreds of datasets might use the same Business Criticality property while carrying different values.
Structured Properties are not DataHub’s only extensibility mechanism, but they provide a useful example of how organization-specific knowledge can be introduced without treating every additional requirement as an entirely new metadata entity type.
The broader architectural principle is:
A metadata platform needs a stable information model while still allowing organizations to extend the knowledge represented within it.
Custom Aspects: Extending the Metadata Model
Structured Properties are useful when we need to attach additional business, governance or operational attributes to existing entities.
But what if our requirement is more complex?
Suppose we want to represent an organization’s internal data certification process, including:
Certification Details │ ├── Certification Level ├── Assessment Date ├── Assessed By ├── Compliance Status └── Next Review Date
Rather than representing everything as individual properties, we may want to introduce a dedicated structured metadata component.
DataHub supports this through Custom Aspects.
A custom aspect allows us to define additional metadata structures using DataHub’s schema-first modelling approach, based on Pegasus/PDL.
Conceptually:
Dataset Entitycustomer_orders │ ├── schemaMetadata ├── ownership ├── upstreamLineage ├── structuredProperties │ └── customCertification │ ├── certificationLevel ├── assessmentDate ├── assessedBy ├── complianceStatus └── nextReviewDate
The customCertification aspect in this example is hypothetical. It illustrates how an organization could introduce a dedicated metadata component alongside DataHub’s existing aspects.
Unlike Structured Properties, Custom Aspects require extending the metadata model and deploying the corresponding model definitions to the DataHub services that need to understand them.
This provides greater flexibility but also introduces additional engineering and operational responsibilities, particularly around model compatibility, deployment and upgrades.
Therefore, choosing between Structured Properties and Custom Aspects is not simply a question of which feature is more powerful.
It is an architectural trade-off between extensibility, complexity and long-term maintainability.
For relatively straightforward organization-specific attributes, Structured Properties may be sufficient.
When a requirement involves a more complex metadata structure or deeper integration with DataHub’s model, Custom Aspects may be more appropriate.
The choice depends on the complexity of the metadata we need to represent and how deeply it must integrate with the platform.
Extensibility is not just about what a platform allows us to model. It is also about the engineering and operational cost of maintaining those extensions.
For enterprise metadata platforms, this becomes an important architectural consideration, particularly when evaluating customization requirements, upgrade compatibility and long-term maintainability.
From Generic Concepts to DataHub
We can now map the generic model from Blog 5 to DataHub’s implementation.
| Generic Concept | DataHub Implementation |
|---|---|
| Entity | Metadata entity, such as Dataset |
| Identity | URN |
| Type | Entity Type |
| Metadata Components | Aspects |
| Extensibility | Structured Properties, Custom Aspects and Custom Entity Types |
| Relationships | Entity references and relationships represented through metadata aspects |
This mapping is useful because it allows us to understand DataHub’s design decisions without memorizing terminology in isolation.
For example:
Why does DataHub need URNs?
Because metadata entities require identity.
Why does it use aspects?
Because different kinds of knowledge describe the same entity and may change independently.
Why does it support Structured Properties?
Because organizations need to represent additional knowledge beyond the standard model.
Why are relationships important?
Because metadata describes a connected ecosystem rather than a collection of isolated objects.
The implementation terminology now follows naturally from the architectural requirements.
How Does OpenMetadata Approach the Same Problem?
DataHub is not the only platform addressing these requirements.
OpenMetadata also represents data assets and related resources as identifiable entities with defined metadata structures.
For example, OpenMetadata provides entity models for datasets and other resources, including tables, pipelines, dashboards and ML models.
It uses entity identifiers and fully qualified names to identify and reference resources.
Its metadata structures can represent information such as descriptions, ownership, tags, schemas and relationships.
OpenMetadata also provides mechanisms such as custom properties to extend entity metadata.
Although the terminology and implementation differ, we can recognize the same underlying requirements.
| Architectural Requirement | DataHub | OpenMetadata |
|---|---|---|
| Represent data assets | Entity Types | Entity Types |
| Identify assets | URNs | Entity IDs and fully qualified names |
| Describe assets | Aspects | Entity metadata structures |
| Extend metadata | Structured Properties and other mechanisms | Custom Properties |
| Connect assets | Entity references and relationships | Entity relationships and lineage |
This table is a conceptual comparison rather than a feature-equivalence assessment.
For example, DataHub aspects and OpenMetadata entity structures are not necessarily equivalent in their update semantics, persistence or API behaviour.
Those differences matter when evaluating platforms.
The point here is that both products address similar architectural problems through different design choices.
What About Google Cloud Knowledge Catalog?
Cloud providers also offer metadata-management capabilities.
Google Cloud Knowledge Catalog, which evolved from Dataplex Universal Catalog, provides another useful example.
Its metadata model includes concepts such as:
- Entries
- Entry Types
- Aspects
- Aspect Types
- Entry Links
These are broadly,
- An entry represents a metadata resource.
- An entry type describes the kind of resource being represented.
- Aspects provide structured metadata associated with entries.
- Aspect types define the structure of those aspects.
- Entry links can represent relationships between entries.
This provides an interesting comparison with DataHub.
Both use the term aspect, but that does not mean the concepts are identical in every implementation detail.
Similarly, an entry in Knowledge Catalog and an entity in DataHub serve related conceptual purposes without necessarily having equivalent APIs, identity semantics or lifecycle behaviour.
The lesson is that we should compare products at the level of architectural requirements before assuming that similarly named concepts behave identically.
What Should We Actually Evaluate in a Metadata Platform?
Once we understand the information model, product evaluation becomes more meaningful. Instead of starting with a feature checklist, we can ask architectural questions.
Identity
Can the platform reliably distinguish assets across systems, environments and organizational boundaries?
Metadata Representation
Can it represent the technical, business, governance and operational knowledge we need?
Extensibility
Can we introduce organization-specific metadata without excessive customization?
Relationships
Can it represent and navigate lineage, ownership, dependencies and other relationships?
Lifecycle
How does it handle creation, updates, synchronization, deprecation and deletion?
Integration
How effectively can it acquire metadata from the systems we already operate?
Governance
Can the platform support our ownership model, classifications and access requirements?
Operations
What does it take to deploy, scale, secure, monitor, upgrade and troubleshoot the platform?
These questions are especially important in enterprise environments.
Two products may provide similar catalog capabilities while differing significantly in their integration architecture, deployment requirements, operational complexity and extensibility.
A product that fits one organization’s architecture may not necessarily be the best choice for another.
The objective of platform evaluation should not simply be to identify the product with the most features, but to understand how well its design fits the organization’s architectural requirements and operating model.
A Metadata Platform Is More Than Its Information Model
We have now seen how the generic metadata concepts from our earlier articles appear in real products.
But representing knowledge is only one part of the problem.
- Consider what happens when a metadata ingestion process discovers a schema change.
- The platform needs to receive that change.
- It needs to identify the correct entity.
- It needs to update the appropriate metadata.
- It may need to persist the new state.
- Search and relationship views may also need to reflect the change.
- Other systems may need to consume it.
And all of this must continue working when individual components fail or become temporarily unavailable.
So behind the metadata model lies another architectural problem.
A metadata platform is also a distributed software system.
It has storage, APIs, ingestion mechanisms, events, indexes, background processing and operational dependencies.
Those components may not all observe the same state at exactly the same moment.
For example, metadata may have been successfully updated in the authoritative metadata store while a search index has not yet reflected the change.
The platform may therefore contain correct metadata that is temporarily difficult to discover.
This creates an important distinction:
Metadata persistence, metadata processing and metadata discoverability are related capabilities, but they are not necessarily the same operation.
Understanding this distinction becomes essential when designing, operating and troubleshooting metadata platforms at scale.
From Metadata Model to Distributed Architecture
We started this article by asking how modern metadata systems represent knowledge.
Using DataHub as our primary example, we explored how entities, URNs, aspects, relationships and Structured Properties map to the generic model we developed earlier.
We also looked briefly at how OpenMetadata and Google Cloud Knowledge Catalog approach similar requirements.
The key takeaway is that product terminology becomes easier to understand once we know the architectural problem each concept is intended to solve.
But now we have reached the next layer.
- We understand what the platform represents.
- We have explored how metadata changes over time.
- And we have seen how real products model that knowledge.
The next question is:
What happens inside a metadata platform when knowledge is created, updated, stored, indexed and made available to consumers?
That takes us into the distributed architecture behind metadata platforms.
Continue the Series
Previous: The Metadata Lifecycle: How Knowledge Is Created, Changed and Kept Current
Next: Inside a Metadata Platform: Storage, Events, Search and Distributed State — Coming soon
Understanding Metadata Systems — Series
This article is part of my Understanding Metadata Systems series, where I explore metadata platforms from first principles—from why metadata exists to how these systems are modelled, implemented and operated.
- Beyond Infrastructure: Seeing the Data & AI Platform as a System
- Why Metadata? When Data Alone Is Not Enough
- Why a Metadata Platform? When Distributed Knowledge Stops Scaling
- Who Owns Metadata? Authority, Accountability and the Operating Model
- Modelling Metadata: From Data Assets to Entities, Identity and Relationships
- The Metadata Lifecycle: How Knowledge Is Created, Changed and Kept Current
- From Model to Platform: How Modern Metadata Systems Represent Knowledge
- Inside a Metadata Platform: Storage, Events, Search and Distributed State — Coming soon
- Operating Metadata at Scale: Reliability, Consistency and Observability — Coming soon
- Metadata for AI: Giving Machines the Context to Understand and Govern Data — Coming soon


Leave a Reply