Understanding DataHub’s Distributed Architecture, Asynchronous Processing and Failure Recovery
A Note for Readers
This is a longer article than the previous parts of the series, and that is intentional.
As we move from conceptual foundations towards practical implementation, I wanted to explore DataHub’s distributed architecture, asynchronous metadata processing, component interactions and operational considerations in sufficient depth to make the discussion genuinely useful.
Rather than splitting these closely related topics into several shorter articles, I have kept them together to provide a more complete picture of how the platform works internally.
If you are exploring, implementing or operating DataHub, I hope this article serves as a useful technical reference that you can revisit as needed.
Understanding Metadata Systems — Part 8
This article is part of my Understanding Metadata Systems series, where I explore metadata platforms from first principles, gradually moving from architectural concepts towards actual product implementations and operations.
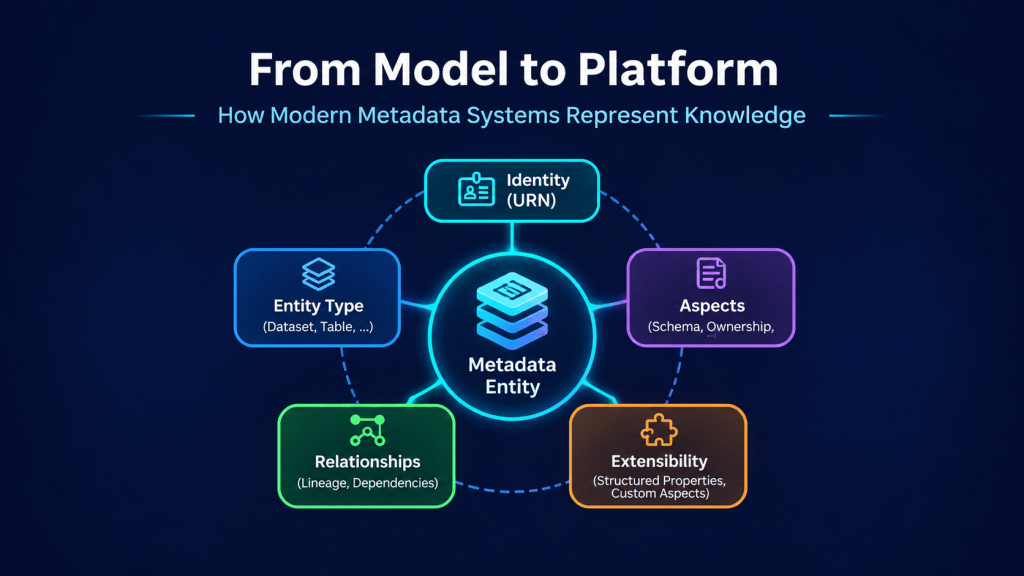
Previous: From Model to Platform: How Modern Metadata Systems Represent Knowledge
From Metadata Modelling to Distributed Architecture
In the previous article, we explored how modern metadata platforms represent knowledge.
Using DataHub as our primary example, we examined entities, URNs, aspects, relationships and extensibility mechanisms such as Structured Properties and Custom Aspects.
We now understand how metadata can be represented.
But that raises another question.
What actually happens inside a metadata platform when metadata is created, updated or removed?
Consider a Snowflake dataset named customer_orders.
- An ingestion process discovers that a new column,
discount_amount, has been added. - The metadata platform needs to reflect this change.
At first glance, this might appear to be a simple database update.
However, several things need to happen.
- The updated metadata must reach the platform.
- The correct entity must be identified.
- The relevant metadata aspect must be updated.
- The change must be persisted.
- Other components may need to be informed.
- Search indexes and relationship representations may need to be updated.
- And the platform must handle failures that occur during these operations.
These important questions need to be addressed while designing the distributed architecture of the metadata platfom:
- What happens if the metadata is persisted successfully but the search index is unavailable?
- What if Kafka is temporarily unavailable?
- What if a consumer processes the same event more than once?
- What if the ingestion process reports success but users cannot find the updated dataset?
These are distributed-systems problems.
In this article, I will primarily use DataHub to explore these questions, drawing on my hands-on experience with its architecture, deployment, integration and operations. While the broader architectural principles apply to other metadata platforms, DataHub provides a practical reference for exploring them in greater depth.
The objective is not to provide another installation tutorial.
Instead, I want to understand how DataHub’s internal components collaborate, how metadata changes propagate through the platform, and how we can reason about its behaviour when something goes wrong.
1. Why Does DataHub Need a Distributed Architecture?
Before examining DataHub’s components, let us consider the workloads a metadata platform must support.
A metadata platform needs to:
- Ingest metadata from different external systems.
- Validate and persist metadata changes.
- Retrieve metadata for known entities.
- Search across potentially millions of entities.
- Maintain relationships and lineage.
- Process metadata changes asynchronously.
- Support event-driven integrations.
- Expose metadata through APIs and user interfaces.
These workloads have different characteristics.
For example, retrieving the schema of a known dataset is fundamentally different from searching for all datasets owned by a particular team.
Similarly, writing a new ownership aspect is different from updating a search index or triggering an external notification when ownership changes.
If every responsibility were tightly coupled into one synchronous operation, the platform would become increasingly difficult to scale and recover.
A more flexible architecture separates responsibilities.
Conceptually:
                Metadata Sources
                       |
                       v
                Ingestion Framework
                       |
                       v
                 Metadata Service
                       |
             +---------+---------+
             |                   |
             v                   v
       Metadata Store       Metadata Events
                                 |
                                 v
                           Event Consumers
                                 |
                        +--------+--------+
                        |                 |
                        v                 v
                  Search Index       Other Actions
                        |
                        v
                 Discovery / APIs
This is a logical representation rather than an exact DataHub deployment diagram.
The important architectural principle is:
A metadata platform separates the responsibility of maintaining metadata state from the responsibility of processing and exposing different representations of that state.
This separation enables independent scaling and recovery.
However, it also introduces asynchronous processing, eventual consistency and partial failures.
2. Understanding DataHub’s Main Architectural Components
DataHub is developed as a collection of services, libraries and supporting infrastructure components.
Its architecture combines a schema-first metadata model, service APIs, event-driven processing and specialized storage systems.
Let us examine the major components.
DataHub Frontend
The frontend provides the user-facing application.
It supports capabilities such as:
- Metadata discovery.
- Dataset and entity exploration.
- Ownership and governance views.
- Lineage navigation.
- Metadata editing.
- Administrative operations.
The frontend communicates with DataHub’s backend APIs.
It is important to understand that the frontend does not independently maintain the authoritative metadata state.
It relies on backend services to retrieve and modify metadata.
Generalized Metadata Service — GMS
GMS is the central metadata service.
It provides APIs for working with DataHub entities and aspects.
Its responsibilities include processing metadata operations, interacting with persistence, retrieving metadata and supporting the metadata services used by other platform components.
For example, an ingestion process may submit an updated schemaMetadata aspect through a GMS API.
GMS processes the operation and coordinates the relevant metadata persistence and change-processing behaviour.
This makes GMS a critical architectural component.
However, GMS is not necessarily responsible for performing every downstream operation synchronously.
Some metadata-related processing can be handled asynchronously through event-driven components.
That distinction becomes particularly important in distributed deployments.
Metadata Database
DataHub uses a relational database, typically MySQL or PostgreSQL, for metadata persistence.
The database maintains persisted entity aspects.
For example:
Entity:customer_ordersAspects: schemaMetadata datasetProperties ownership upstreamLineage status
These aspects represent different categories of knowledge associated with the same entity.
The relational database is the system of record for the persisted aspect state within DataHub.
However, it is not necessarily the original authority for the information represented.
Snowflake may remain authoritative for a table’s physical schema.
The business domain may remain authoritative for its business meaning.
DataHub maintains its representation of that information.
Kafka
Kafka supports asynchronous communication between components.
It allows metadata-related messages to be produced, stored in topics and consumed by other services.
This decouples message production from downstream processing.
A component producing an event does not necessarily need to wait for every downstream consumer to finish processing it.
Kafka therefore plays an important role in metadata change propagation.
Elasticsearch or OpenSearch
DataHub uses a search engine to support discovery and search-oriented workloads.
The search engine maintains indexed representations of metadata.
These representations are optimized for search, filtering and related retrieval patterns.
They are not simply another copy of the relational metadata database.
A search document may contain selected fields derived from multiple metadata aspects.
This creates an important distinction:
Persisted metadata state and indexed metadata state are separate representations.
Metadata Processing Consumers
DataHub includes background processing capabilities for handling metadata-related events.
Depending on the DataHub version and deployment topology, these may be exposed through components with names such as:
- Metadata Change Event Consumer.
- Metadata Audit Event Consumer.
- Other metadata processing services.
The exact responsibilities and component boundaries depend on the release and configuration.
These consumers participate in processing metadata changes and maintaining derived representations.
We will examine their relationship with MCP and MCL shortly.
DataHub Actions
DataHub Actions provides a framework for reacting to metadata events and integrating DataHub with external systems.
For example, an action could respond to an ownership change by invoking an external workflow or sending a notification.
Actions is particularly useful when metadata changes need to trigger behaviour outside the core metadata platform.
It should not, however, be confused with the ingestion framework itself.
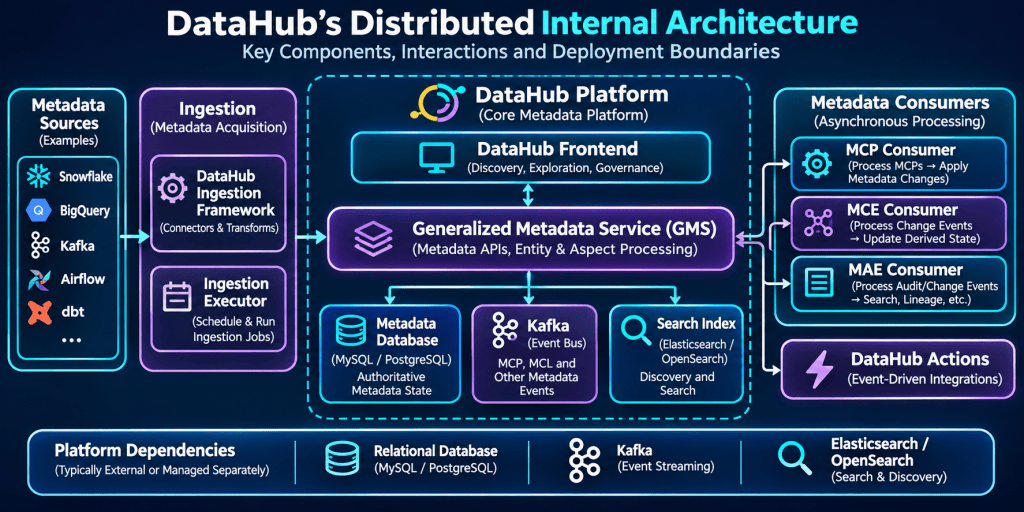
High-level view of DataHub’s core services, metadata ingestion framework, asynchronous processing components (MCP, MCE and MAE consumers), DataHub Actions and supporting infrastructure. The diagram illustrates logical responsibilities and deployment boundaries; actual component topology and event-processing responsibilities may vary across DataHub versions.
3. How DataHub Stores Metadata Internally
In Part 7, we explored DataHub’s aspect-based metadata model.
Let us now connect that model to persistence.
A DataHub entity is identified by a URN.
For example:
urn:li:dataset:( urn:li:dataPlatform:snowflake, PRODUCTION.COMMERCE.CUSTOMER_ORDERS, PROD)
The same entity may have multiple aspects.
Conceptually:
| URN | Aspect | Version | Metadata |
|---|---|---|---|
| customer_orders | schemaMetadata | 0 | Dataset schema |
| customer_orders | ownership | 0 | Commerce Team |
| customer_orders | datasetProperties | 0 | Description |
| customer_orders | upstreamLineage | 0 | Upstream datasets |
| customer_orders | status | 0 | Removal status |
The URN is abbreviated here for readability.
In DataHub’s relational persistence model, the metadata_aspect_v2 table is particularly important.
It stores serialized metadata aspects associated with entity URNs.
The latest aspect state is commonly represented using version 0, with historical versions managed according to the implementation and retention configuration.
The presence of version fields does not imply that every historical change is retained indefinitely.
Why is aspect-level persistence useful?
Consider a dataset whose schema and ownership change independently.
At 10:00 AM, an ingestion process updates schemaMetadata.
At 11:00 AM, a domain owner updates ownership.
Both changes concern the same dataset, but they modify different aspects.
This allows the platform to represent different categories of knowledge without treating every change as a complete replacement of the entity.
It also supports the separation of metadata producers and authorities discussed earlier in this series.
However, aspect-level modelling does not automatically eliminate concurrency or ownership conflicts.
For example, two ingestion processes updating the same aspect may still overwrite one another depending on their update semantics.
The metadata model provides the structure.
The ingestion design and operating model determine how changes should be coordinated.
4. Where Does Metadata Ingestion Actually Run?
Before discussing MCP and MCL, we need to understand how metadata enters DataHub.
DataHub provides an ingestion framework with connectors for different metadata sources.
These connectors can extract metadata from systems such as:
- Snowflake.
- BigQuery.
- Kafka.
- Airflow.
- dbt.
- Other supported data and analytics systems.
A typical ingestion pipeline consists of:
Source Connector | vMetadata Extraction | vMetadata Transformation | vDataHub Sink | vDataHub Platform
The source connector communicates with the external system.
It discovers metadata and converts that information into DataHub-compatible metadata records.
The sink submits those records to DataHub.
Does ingestion run inside GMS?
Not necessarily.
This is an important architectural distinction.
The ingestion framework is a separate execution capability.
It can run:
- As a standalone process.
- Inside a container.
- As a scheduled Kubernetes workload.
- Through an external workflow orchestrator.
- Through supported DataHub-managed ingestion execution mechanisms.
For example, an organization may run ingestion pipelines using Airflow or another orchestration platform.
The ingestion process communicates with DataHub through its supported sink.
GMS receives and processes metadata operations, but it does not need to execute the source connector itself.
This separation is useful in production environments.
Metadata extraction may involve expensive queries, external API calls, network dependencies and long-running jobs.
Those workloads can be isolated from the metadata service.
What about DataHub’s managed ingestion?
DataHub also supports ingestion execution and management capabilities through its ingestion ecosystem.
In deployments using DataHub’s ingestion executor infrastructure, ingestion jobs may be launched and managed separately from the core metadata API service.
The exact executor architecture depends on the product version and deployment configuration.
The important distinction is between:
Ingestion execution, which acquires metadata from external systems, and metadata processing, which applies that metadata within DataHub.
They are different responsibilities and may run in different processes or infrastructure environments.
5. Understanding MCP: Metadata Change Proposal
Now we can examine how metadata changes are represented.
DataHub uses the concept of a Metadata Change Proposal, or MCP.
An MCP represents a proposed mutation to metadata.
For example, suppose the Snowflake ingestion connector discovers an updated schema.
Conceptually, it produces a metadata proposal containing:
Entity URN:customer_ordersAspect:schemaMetadataChange Type:UPSERTProposed Metadata:Updated schema including discount_amount
This is a simplified representation.
The actual MCP format includes structured fields defined by DataHub’s metadata model.
An MCP can represent operations such as updating an aspect or removing metadata, depending on the supported change type and processing path.
The important point is:
An MCP describes the metadata change that should be applied. It does not, by itself, prove that the change has been persisted.
The proposal must be processed.
That processing may occur through different submission paths.
6. Synchronous Metadata Ingestion
One common approach is submitting MCPs through DataHub’s REST-based ingestion path.
Conceptually:
Snowflake | vDataHub Ingestion Framework | vREST Sink | vGMS | vMetadata Processing | vMetadata Database
The ingestion process communicates directly with GMS.
GMS processes the metadata operation and persists the resulting state.
Depending on the implementation and configuration, metadata change events are also produced for downstream processing.
What does synchronous mean here?
It is important not to interpret synchronous ingestion as meaning that every downstream operation has completed.
A successful response from the metadata API may confirm that the request has reached a particular processing milestone.
It does not automatically guarantee that:
- Search indexing has completed.
- Every downstream consumer has processed the change.
- Every relationship projection is updated.
- External Actions have finished executing.
The precise acknowledgment semantics depend on the API and DataHub version.
This distinction is important when troubleshooting.
An ingestion job can report successful metadata submission while a downstream search representation is still catching up.
7. Asynchronous Metadata Ingestion Through Kafka
DataHub also supports asynchronous metadata submission through Kafka-based mechanisms.
In this approach, the ingestion process produces metadata proposals to a Kafka topic.
A consumer subsequently processes those proposals.
Conceptually:
Snowflake | vDataHub Ingestion Framework | vKafka Producer | vMetadata Change Proposal Topic | vKafka Consumer | vMetadata Processing | vMetadata Database
The significant architectural difference is the boundary introduced by Kafka.
The ingestion producer and metadata processor are no longer required to execute as one direct request-response operation.
The producer submits a message.
The consumer processes it asynchronously.
What does the Kafka producer do?
A Kafka producer publishes messages to a Kafka topic.
For metadata ingestion, the message contains the metadata change proposal.
Kafka stores the message according to the topic’s configuration and durability guarantees.
Once the broker acknowledges the publication according to the producer configuration, the producer knows the message has reached the corresponding Kafka acknowledgment milestone.
That does not mean DataHub has already applied the metadata change.
What does the Kafka consumer do?
A consumer subscribes to the relevant topic.
It reads messages and processes them.
For MCP processing, this involves applying the proposed metadata mutation through DataHub’s metadata processing logic.
Successful processing can result in updated persisted metadata state.
The consumer also needs to manage progress through Kafka offsets.
An offset identifies a position within a Kafka partition.
The relationship between successful processing and offset commitment is important for recovery.
For example, if a consumer processes a message but fails before committing its offset, the message may be delivered again.
This is one reason event-driven systems must consider idempotency.
Why does this matter?
A metadata update may be processed more than once following retries or recovery.
The processing design must avoid unintended effects from repeated delivery.
Similarly, an ingestion producer may successfully publish a message while the consumer is temporarily unavailable.
The message can remain in Kafka until it is processed, subject to retention and other operational constraints.
This provides useful decoupling, but it introduces consumer lag and recovery considerations.
8. MCP and MCL: Two Different Stages of a Metadata Change
We have discussed MCPs.
Now let us introduce Metadata Change Logs, or MCLs.
These two concepts represent different stages in the metadata change lifecycle.
MCP — The Proposed Change
An MCP expresses the intended mutation.
For example:
Update the schemaMetadata aspectfor customer_orders.
MCL — The Processed Change
An MCL describes a metadata change that has been processed through DataHub’s metadata mutation path.
Conceptually:
The schemaMetadata aspectfor customer_orders changed.
MCL events can include information about the entity, aspect and change, allowing downstream consumers to react.
The distinction can be summarized as:
| Concept | MCP | MCL |
|---|---|---|
| Full name | Metadata Change Proposal | Metadata Change Log |
| Purpose | Request a metadata mutation | Communicate a processed metadata change |
| Typical producer | Ingestion framework or metadata client | DataHub metadata processing |
| Typical consumer | Metadata processing service | Downstream metadata consumers |
| Relationship to persistence | Proposed operation | Associated with processed metadata changes |
| Architectural role | Command-like message | Change notification/event |
This is a conceptual comparison.
The actual payload structures and supported operations are defined by DataHub’s metadata model.
The important architectural distinction is:
MCP represents the intention to change metadata. MCL communicates the result of metadata change processing to downstream components.
9. Where Do MCE and MAE Fit?
This is an area where DataHub terminology can become confusing.
Readers may encounter:
- MCP.
- MCL.
- MCE.
- MAE.
- MCE Consumer.
- MAE Consumer.
These names do not all refer to the same category of component.
MCE — Metadata Change Event
Metadata Change Event is an older event representation used in DataHub’s metadata ingestion architecture.
Historically, MCEs could carry metadata snapshots describing changes to an entity.
The newer MCP model provides a more aspect-oriented mechanism for expressing metadata mutations.
Conceptually, both concern changes to metadata, but their structure and processing semantics differ.
An MCE should not simply be treated as another name for an MCP.
MAE — Metadata Audit Event
Metadata Audit Event is associated with DataHub’s older metadata change and audit event architecture.
It represents information about metadata changes that can be consumed by downstream processing components.
MCL is the newer terminology and event model used for communicating processed metadata changes.
Again, the concepts are related, but they should not be treated as identical payload formats.
What about MCE and MAE consumers?
The terminology becomes more confusing because DataHub deployments have also used component names such as:
datahub-mce-consumer
and
datahub-mae-consumer
These are names of executable processing components.
They should not be confused with the event schemas themselves.
Depending on the DataHub release, deployment configuration and migration history, these services may participate in processing metadata proposals, change logs and related metadata events.
Therefore, the component name alone does not establish exactly which message types it processes.
For example, it would be incorrect to assume that an MCE-named consumer can only process legacy MCE payloads.
Likewise, the MAE consumer name should not be interpreted as proof that it exclusively consumes legacy MAE messages.
The actual responsibilities must be checked against the deployed release.
Why is this distinction important?
When designing or troubleshooting a distributed deployment, we need to distinguish three things:
The message format
What kind of metadata event is being exchanged?
The processing responsibility
What work must be performed when the message is received?
The deployed component
Which executable service performs that work?
These are related but separate architectural concerns.
A useful mental model is:
Metadata Change | vMessage Representation(MCP / MCL / legacy formats) | vProcessing Responsibility(Apply / Propagate / Index) | vRuntime Component(GMS / Metadata Consumers)
This distinction also helps when upgrading DataHub, because message models and consumer deployment topology can evolve independently.
10. How Metadata Changes Propagate Through DataHub
Let us now connect the components into an end-to-end flow.
Suppose the customer_orders schema changes in Snowflake.
Stage 1 — Metadata Extraction
The ingestion connector queries Snowflake metadata interfaces.
It discovers the new column.
The connector constructs an updated representation of the dataset schema.
Stage 2 — Metadata Proposal
The ingestion framework produces an MCP for the schemaMetadata aspect.
The MCP identifies the dataset and the proposed new aspect value.
Stage 3 — Metadata Submission
The proposal is submitted through a supported sink.
This may involve a direct API call to GMS or publication to a Kafka topic for asynchronous processing.
Stage 4 — Metadata Processing
DataHub processes the proposal.
The corresponding aspect state is updated according to the operation and the platform’s processing rules.
Stage 5 — Metadata Persistence
The updated aspect is persisted in the relational metadata store.
At this stage, the database can contain the new schema even if downstream representations have not yet been updated.
Stage 6 — Change Propagation
The metadata processing path produces change information for downstream consumers.
MCL events are an important mechanism for this.
Stage 7 — Asynchronous Consumption
Consumers process metadata change events.
Depending on the event and implementation, this may involve updating search indexes and other derived metadata representations.
Stage 8 — Discovery
The updated metadata becomes available through the relevant search and discovery capabilities once the corresponding projections have been updated.
Conceptually:
                  Snowflake
                      |
                      v
              Ingestion Framework
                      |
                      v
                     MCP
                      |
            +---------+---------+
            |                   |
            v                   v
       REST Submission     Kafka Submission
            |                   |
            v                   v
           GMS           MCP Processing
            |                   |
            +---------+---------+
                      |
                      v
              Metadata Processing
                      |
                      v
               Metadata Database
                      |
                      v
               Change Publication
                      |
                      v
                 MCL Events
                      |
                      v
              Metadata Consumers
                      |
                      v
              Derived Projections
                      |
                      v
                Search / APIs
This is a logical flow.
It deliberately does not claim that database persistence and event publication form one atomic transaction in every DataHub version.
The exact ordering, acknowledgment and recovery guarantees must be understood from the relevant implementation.
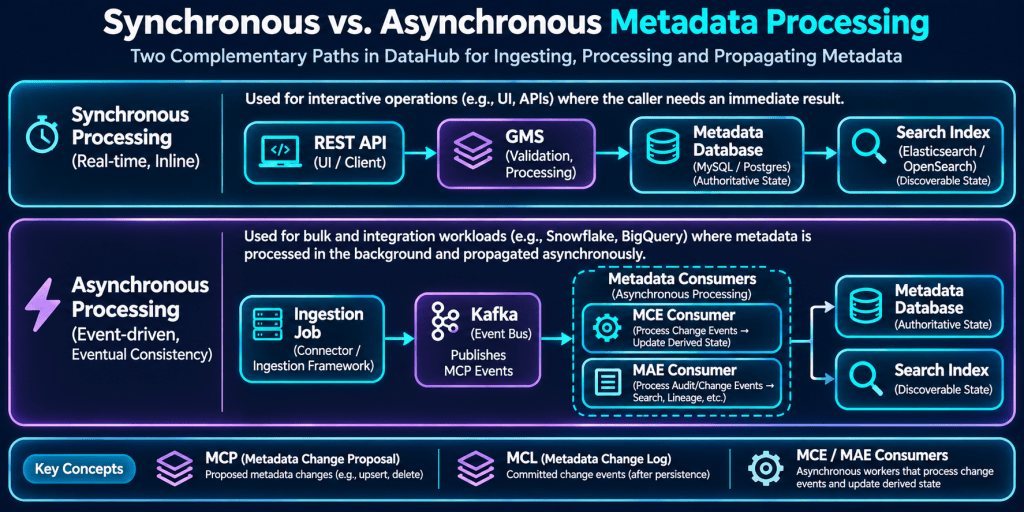
Comparison of REST-based synchronous metadata submission and Kafka-based asynchronous MCP processing. Both paths ultimately update persisted metadata and can trigger downstream MCL-driven processing. The diagram illustrates the distinction between metadata submission, persistence and search indexing, which may complete at different times. Consumer responsibilities and deployment topology vary by DataHub version.
11. How Kafka Enables Asynchronous Processing
Kafka is not simply a transport mechanism in this architecture.
It provides a durable, partitioned event log that supports decoupled processing.
Let us examine the relevant concepts.
Topics
A Kafka topic is a logical stream of messages.
DataHub uses different event streams for different metadata-processing purposes.
The exact topic names and configurations depend on the DataHub version and deployment.
Producers
Producers publish messages to topics.
An ingestion process using a Kafka sink is one example of a producer.
Metadata processing services can also produce change events.
Consumers
Consumers subscribe to topics and process messages.
For example, a metadata processing consumer may process MCP messages.
Another consumer may react to MCL events and update a search projection.
Consumer Groups
Kafka consumer groups allow multiple consumer instances to share processing responsibility for partitions of a topic.
Within a consumer group, a partition is assigned to one active consumer at a time.
This enables horizontal scaling, subject to partition count and processing characteristics.
Offsets
Offsets identify positions within Kafka partitions.
Consumers use offsets to track processing progress.
If processing stops, consumers can resume according to their committed offsets and recovery configuration.
Ordering
Kafka provides ordering within a partition.
It does not provide a single global ordering across all partitions.
Therefore, metadata event processing must be designed with the relevant ordering requirements in mind.
For example, changes affecting the same entity or aspect may need consistent partitioning and appropriate update semantics.
Consumer Lag
Consumer lag indicates the difference between messages available in a partition and the consumer group’s committed progress.
Increasing lag can indicate that consumers are unable to keep up with incoming events.
However, low lag alone does not prove that the resulting metadata state is correct.
A consumer may process messages successfully while downstream application-level errors or modelling issues still exist.
This is another example of the difference between operational progress and semantic correctness.
12. Search Indexing and Derived Metadata State
Why does DataHub maintain a separate search engine?
Because searching metadata is a different workload from retrieving a known aspect.
Consider two queries.
Query A
Retrieve the schema of a dataset whose URN is already known.
Query B
Find all datasets containing customer information, owned by a particular team and classified as sensitive.
The first is a targeted metadata retrieval.
The second requires discovery across a potentially large metadata population.
DataHub uses Elasticsearch or OpenSearch to maintain search-oriented representations.
These indexes may contain fields derived from multiple metadata aspects.
For example:
Dataset:customer_ordersPersisted Aspects: schemaMetadata ownership datasetProperties globalTags status
A search document may expose selected information such as:
Entity URNDataset NameDescriptionOwnerTagsPlatformEnvironmentSearchable Schema Fields
The exact indexed fields depend on DataHub’s search model and configuration.
The important distinction is:
The relational metadata store maintains persisted aspect state.
The search engine maintains a derived representation optimized for discovery.
What happens when these representations disagree?
Suppose the database contains the updated schema. However, the relevant search update has not completed.
An API retrieving the persisted aspect may return the updated schema.
A search operation relying on stale indexed fields may still reflect the previous state.
This is an example of eventual consistency between persisted metadata and a derived representation.
The same architectural issue can affect other metadata-derived capabilities.
The key lesson is:
Successful metadata persistence does not necessarily mean every downstream representation has already converged.
13. Eventual Consistency Versus Persistent Divergence
Eventual consistency is often described as a normal characteristic of distributed systems.
But we should distinguish between two different conditions.
Temporary Propagation Delay
- A metadata change has been persisted.
- The corresponding event is waiting to be processed.
- The consumer is healthy and eventually processes the event.
- The search index catches up.
This is expected asynchronous behaviour.
Persistent State Divergence
- A metadata change has been persisted.
- However, downstream processing fails repeatedly, a required event is missed, or a derived representation becomes inconsistent.
- The search index does not converge with the persisted state.
- This is no longer simply a normal propagation delay.
- It is a recovery problem.
This distinction matters operationally.
A missing dataset in search could result from:
- An ingestion failure.
- Incorrect source permissions.
- An entity identity mismatch.
- A metadata processing failure.
- Consumer lag.
- Search indexing failure.
- Search filtering.
- A stale or inconsistent index.
- An entity status change.
The symptom is the same.
The root causes are different.
A reliable metadata platform therefore needs mechanisms for detecting and recovering from divergence.
14. Where Does DataHub Actions Fit?
So far, we have focused on the core metadata processing path.
But metadata changes may also need to trigger behaviour outside DataHub.
For example:
- Notify a team when ownership changes.
- Trigger a governance workflow.
- Synchronize metadata with another system.
- Initiate an external validation process.
- React to changes in classifications or tags.
This is where DataHub Actions becomes relevant.
DataHub Actions provides an event-driven framework for defining actions that respond to metadata events.
Conceptually:
Metadata Change | vMCL Event | vKafka | vDataHub Actions | +----> Notification | +----> External API | +----> Governance Workflow | +----> Custom Integration
Actions can be deployed separately from the core metadata service.
This provides another form of workload isolation.
For example, an external notification service becoming unavailable should not automatically require the metadata ingestion process itself to wait for that notification to complete.
The actual isolation and failure behaviour depend on how the action is implemented.
Actions versus ingestion
It is important not to confuse the two.
The ingestion framework acquires metadata from external systems and submits it to DataHub.
Actions reacts to events and performs configured behaviour.
An action may invoke an ingestion-related workflow or interact with another metadata system, but that does not make Actions the universal execution environment for DataHub ingestion.
This separation allows organizations to choose appropriate execution environments for different workloads.
15. Understanding DataHub’s Deployment Architecture
We have now examined the logical components.
How does this translate into deployment?
A relatively simple DataHub deployment may include:
DataHub FrontendDataHub GMSMetadata ConsumersActionsMySQLKafkaElasticsearchSupporting Dependencies
These components may initially be deployed within one Kubernetes cluster.
This can be convenient for development, experimentation and smaller environments.
However, production requirements often introduce additional considerations.
For example:
- Database durability and backups.
- Kafka availability and throughput.
- Search cluster capacity.
- Independent scaling of services.
- Network isolation.
- Security and access control.
- Upgrade procedures.
- Recovery objectives.
- Operational ownership.
A production architecture may therefore separate the stateless application components from the stateful infrastructure dependencies.
Conceptually:
                  Kubernetes Cluster
                +----------------------+
                |                      |
                |  DataHub Frontend    |
                |                      |
                |  DataHub GMS         |
                |                      |
                |  Metadata Consumers  |
                |                      |
                |  DataHub Actions     |
                |                      |
                +----------+-----------+
                           |
              +------------+------------+
              |            |            |
              v            v            v
          Managed       Managed      Search
          Database       Kafka       Cluster
The database, Kafka and search services may be externally managed or independently operated.
The specific choice depends on organizational requirements and available infrastructure.
This approach can reduce the operational coupling between application deployments and stateful infrastructure.
However, it also introduces network, authentication, connectivity and dependency-management requirements.
16. Separating Metadata Consumers from GMS
One architectural decision worth examining is how metadata processing workloads are distributed.
GMS serves metadata APIs and coordinates metadata operations.
Asynchronous consumers perform other processing responsibilities.
These workloads have different scaling characteristics.
For example, GMS may experience high API traffic while a consumer experiences a backlog of metadata events.
If both workloads compete for the same constrained runtime resources, one can affect the other.
Separating consumer processing into dedicated deployments can provide better resource isolation.
Conceptually:
                  GMS Deployment
                  --------------
                  Metadata APIs
                  Metadata Processing
                  Persistence Access


                Consumer Deployments
                --------------------
                MCP / MCL Processing
                Search Updates
                Derived State Updates
The precise responsibilities depend on the DataHub release.
This is not simply about moving containers into separate Kubernetes Deployments.
It is about understanding which processing responsibilities belong to which runtime components.
Potential benefits
Independent consumer deployments can provide:
Resource isolation
Consumer CPU and memory usage can be managed separately from GMS.
Independent scaling
Consumer replicas and resources can be adjusted according to processing demand.
Operational visibility
Consumer-specific failures and resource consumption become easier to distinguish.
Failure isolation
Some consumer failures can be investigated and recovered without restarting unrelated services.
However, separation does not automatically guarantee lower GMS load.
GMS may still perform substantial work for metadata processing, persistence and APIs.
The benefit depends on which responsibilities are actually moved and how the deployed version implements them.
It is therefore important to measure the result rather than assume that separating components eliminates all processing overhead from GMS.
17. Refactoring the Official Helm Deployment for a Distributed Architecture
DataHub provides official Helm charts for deploying the platform and its dependencies.
A common starting point is to use the supported chart structure with the required prerequisites.
This is useful for understanding the components and establishing a working environment.
However, enterprise production requirements may call for a different topology.
For example:
- An externally managed relational database.
- An independently managed Kafka service.
- A separately operated search cluster.
- Dedicated consumer deployments.
- Independent resource configurations.
- Different networking and security boundaries.
Does this mean we need to abandon the official Helm charts and create an entirely new deployment framework?
Not necessarily.
In many cases, the better approach is to adapt the supported Helm deployment through configuration and carefully controlled extensions.
The objective should be to preserve the product’s supported deployment lifecycle while adjusting its topology to meet enterprise requirements.
Separate application deployment from prerequisites
The first step is to distinguish DataHub application components from infrastructure dependencies.
The prerequisite chart is convenient for deploying supporting services.
However, a production architecture may use externally managed equivalents.
The application chart can then be configured to connect to those services.
Preserve official application templates
Where possible, retain the official templates for DataHub components.
Use supported configuration values to control:
- Component enablement.
- Replica counts.
- Resource requests and limits.
- External service endpoints.
- Authentication and secrets.
- Service configuration.
- Ingress and networking.
This reduces the need to maintain a completely separate deployment implementation.
Introduce controlled workload separation
If the desired consumer topology is supported by the selected chart version, configure the relevant consumer workloads independently.
Where the official chart does not expose the required topology directly, additional templates or a narrowly scoped overlay may be necessary.
Such extensions should remain small and version-controlled.
They should not silently duplicate processing responsibilities.
For example, if a consumer responsibility is moved to a dedicated deployment, the original execution path must be reviewed to avoid unintended duplicate processing.
Maintain upgrade compatibility
A customized deployment should still have a predictable upgrade path.
That means understanding:
- Which chart values are supported.
- Which templates have been overridden.
- Which components are enabled.
- Which image versions are compatible.
- Which metadata migrations are required.
- Which consumer responsibilities have changed between releases.
The architectural principle is:
Customize the deployment topology where necessary, but avoid unnecessarily replacing the product’s supported deployment lifecycle.
This is particularly important for a metadata platform that will be upgraded and operated over several years.
18. A Practical End-to-End Example
Let us bring everything together using customer_orders.
Assume the dataset initially contains:
order_idcustomer_idorder_dateorder_amount
A new column is added:
discount_amount
Step 1 — Source Metadata Changes
The physical schema changes in Snowflake.
Snowflake remains authoritative for that schema.
Step 2 — Ingestion Discovers the Change
The Snowflake connector queries the relevant metadata interfaces.
It identifies the updated schema.
Step 3 — MCP Is Generated
The ingestion framework produces an updated schemaMetadata aspect proposal.
Step 4 — MCP Is Submitted
The proposal reaches DataHub through the configured sink.
For REST ingestion, this involves a direct API submission.
For Kafka-based ingestion, the proposal is published to the relevant topic and processed asynchronously.
Step 5 — Metadata Is Persisted
DataHub processes the proposal and updates the persisted aspect state.
Step 6 — MCL Is Produced
The processed metadata change is communicated through the relevant change-log mechanism.
Step 7 — Consumers Process the Change
Downstream consumers receive the event and perform their configured processing.
This may include updating search-oriented representations.
Step 8 — Search Reflects the Change
Once the relevant search projection is updated, the changed metadata becomes discoverable through search capabilities that index those fields.
Step 9 — External Actions May React
If configured, an action may respond to the change.
For example, an external governance workflow could be notified.
Step 10 — Consumers Observe the Updated Metadata
Users and applications retrieve or discover the updated metadata through DataHub’s supported interfaces.
This sequence demonstrates how a single source-system change can cross several architectural boundaries.
It also gives us a practical way to investigate failures.
19. Troubleshooting Through Architectural Boundaries
Suppose the updated schema is not visible in DataHub.
Rather than immediately restarting services, we can investigate the processing path.
Boundary 1 — Source to Ingestion
Did the ingestion connector discover the new schema?
Check the source permissions, ingestion configuration, filters and execution logs.
If the connector never discovered the change, the problem is upstream of DataHub’s persistence layer.
Boundary 2 — Ingestion to Submission
Was the MCP generated and submitted?
For REST-based ingestion, inspect the sink response and errors.
For Kafka-based ingestion, verify message publication and broker connectivity.
A successful extraction does not prove successful submission.
Boundary 3 — Submission to Persistence
Was the proposed metadata change processed?
Check the relevant processing component and GMS logs.
Inspect the persisted aspect through the supported metadata APIs.
Where appropriate, database inspection can help establish whether the expected aspect state exists.
Boundary 4 — Persistence to Event Propagation
Was the metadata change communicated to downstream processing?
Investigate the relevant event stream and processing logs.
The exact checks depend on the deployed DataHub version.
Boundary 5 — Event Consumption
Are the relevant consumers healthy?
Are they processing messages?
Is consumer lag increasing?
Are there repeated processing failures?
Boundary 6 — Search Index
Does the expected entity exist in the relevant search index?
Are the required fields indexed?
Could search filters or entity status explain the missing result?
Boundary 7 — User-Facing Discovery
Does the API return the expected entity?
Does search return it?
Does the frontend apply additional filtering or visibility rules?
These questions help isolate the problem.
A useful diagnostic sequence is:
Source | vIngestion | vMCP Submission | vMetadata Processing | vPersisted Aspect | vMCL Processing | vSearch Projection | vDiscovery
At each boundary, we should establish whether the expected state or event exists before moving downstream.
This is often more effective than treating a missing search result as a generic application failure.
20. Practical Failure Scenarios
Let us examine a few common failure categories.
| Failure | Possible Impact | Investigation |
|---|---|---|
| Ingestion connector failure | Source changes not acquired | Connector logs, permissions, filters |
| REST submission failure | Metadata mutation not accepted | Sink response, GMS availability |
| Kafka publication failure | Asynchronous proposal not delivered | Producer errors, broker connectivity |
| MCP consumer failure | Proposals not processed | Consumer logs, lag, offsets |
| Metadata database failure | Persistence and retrieval degraded | Database health, connectivity |
| MCL processing failure | Derived representations become stale | Event stream, consumer logs |
| Search engine failure | Discovery degraded | Search health, indexing errors |
| Actions failure | External workflows not completed | Action logs, retries, dependencies |
| Source permissions change | Partial or missing metadata | Source authorization, ingestion reports |
The important point is that these failures affect different parts of the platform.
A metadata database outage is not the same as a search-indexing failure.
An ingestion failure is not the same as an event-processing backlog.
And a healthy GMS service does not guarantee that all metadata is current.
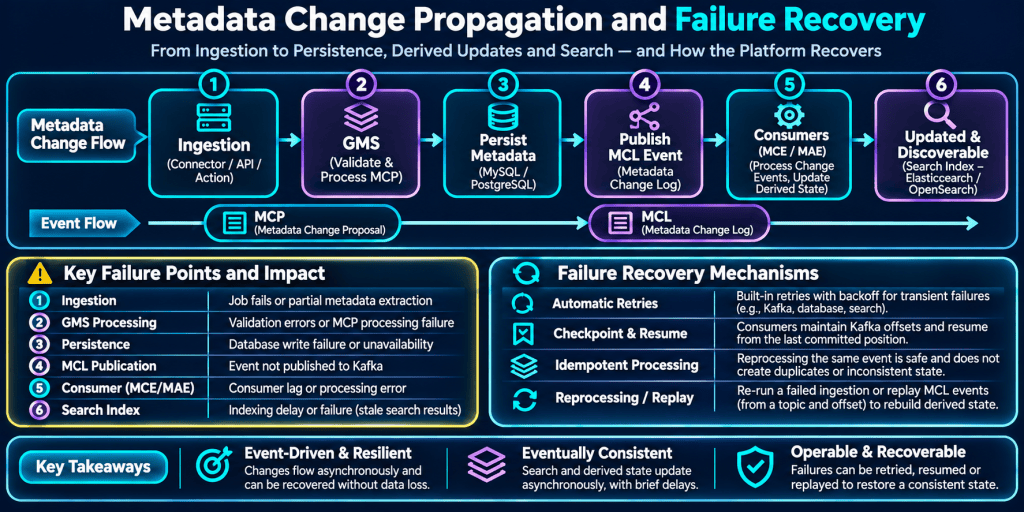
End-to-end view of metadata change propagation through ingestion, GMS, persistence, MCL publication, asynchronous consumers and search indexing. The diagram highlights potential failure points and recovery approaches, including retries, Kafka offset management, idempotent processing and event replay. Actual recovery capabilities and guarantees depend on the DataHub version, component configuration and operational procedures.
21. What Should We Consider When Designing a Production Deployment?
Once we understand the architecture, production design becomes a question of balancing several concerns.
Availability
Which components are critical to metadata ingestion, retrieval and discovery?
Which failures cause complete outages, and which cause partial degradation?
Scalability
Can GMS, consumers and search scale according to their workloads?
Are Kafka partitions and consumer groups configured appropriately?
Persistence
How are metadata database backups, recovery and migrations handled?
How is historical metadata retention managed?
Event Processing
What happens when consumers fail?
Can messages be retried or replayed?
How are processing errors detected?
Search Recovery
Can indexes be rebuilt when derived state becomes inconsistent?
How are indexing failures identified?
Security
How do components authenticate with external services?
How are network boundaries, credentials and service identities managed?
Upgradeability
Can the deployment adopt newer DataHub releases without extensive rework?
Are customizations limited and documented?
Observability
Can we determine whether metadata is being acquired, processed, persisted and made discoverable?
These considerations demonstrate why production readiness is not simply a matter of increasing replica counts.
A distributed metadata platform needs a coherent operating model.
22. The Architectural Trade-off: Decoupling Versus Complexity
DataHub’s distributed architecture provides several benefits.
- Different workloads can be separated.
- Stateful dependencies can be managed independently.
- Asynchronous processing can reduce coupling between metadata mutations and downstream work.
- Search can be optimized for discovery.
- External integrations can react to metadata changes.
However, these benefits introduce complexity.
- More components mean more failure boundaries.
- Asynchronous processing introduces propagation delays.
- Multiple representations create consistency concerns.
- Independent deployments require coordinated upgrades.
- Event-driven processing requires recovery and idempotency considerations.
The objective is not to eliminate this complexity entirely.
It is to understand why the complexity exists and manage it deliberately.
A distributed metadata platform trades some implementation simplicity for flexibility, scalability and workload isolation. The architecture becomes reliable only when its consistency and recovery mechanisms are understood and operated effectively.
23. From Understanding the Architecture to Operating It Reliably
We started with a simple question:
What happens when a metadata source changes?
Following that change through DataHub revealed several architectural layers.
- The ingestion framework acquires metadata.
- MCPs express proposed changes.
- Metadata processing applies those changes.
- The relational database maintains persisted aspect state.
- MCLs communicate processed changes.
- Kafka enables asynchronous propagation.
- Consumers maintain derived representations.
- Search engines support discovery.
- Actions can trigger external workflows.
- And the deployment architecture determines how these responsibilities are distributed across runtime components.
The most important lesson is that a metadata platform does not maintain just one representation of knowledge.
It coordinates multiple representations serving different purposes.
Those representations may observe changes at different times.
They may also fail independently.
Understanding the processing flow helps us identify where a problem originates.
But operating such a platform reliably requires another layer of engineering.
- How do we measure ingestion freshness?
- How do we monitor Kafka consumer lag?
- How do we detect indexing failures?
- How do we distinguish temporary propagation delay from persistent divergence?
- How do we define meaningful reliability objectives for metadata discovery and correctness?
These are the questions I will explore in the next article.
Next: Operating Metadata at Scale: Reliability, Consistency and Observability
Continue the Series
Previous: From Model to Platform: How Modern Metadata Systems Represent Knowledge
Next: Operating Metadata at Scale: Reliability, Consistency and Observability — Coming soon
Understanding Metadata Systems — Series
This article is part of my Understanding Metadata Systems series, where I explore metadata platforms from first principles—from why metadata exists to how these systems are modelled, implemented and operated.
- Beyond Infrastructure: Seeing the Data & AI Platform as a System
- Why Metadata? When Data Alone Is Not Enough
- Why a Metadata Platform? When Distributed Knowledge Stops Scaling
- Who Owns Metadata? Authority, Accountability and the Operating Model
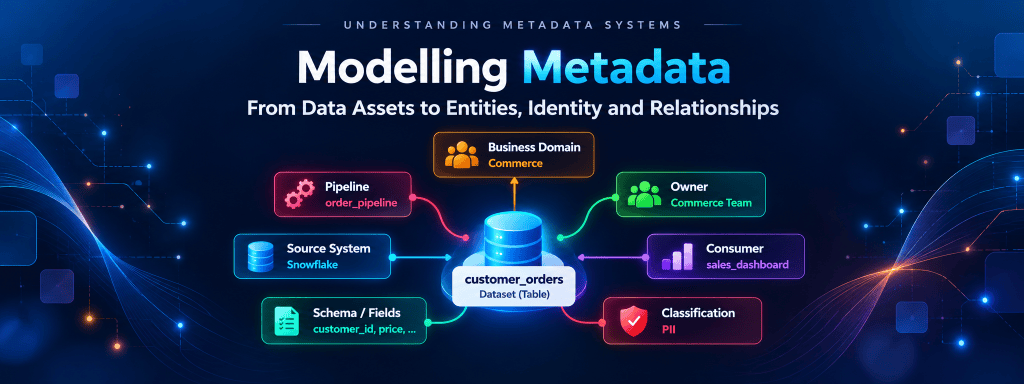
- Modelling Metadata: From Data Assets to Entities, Identity and Relationships
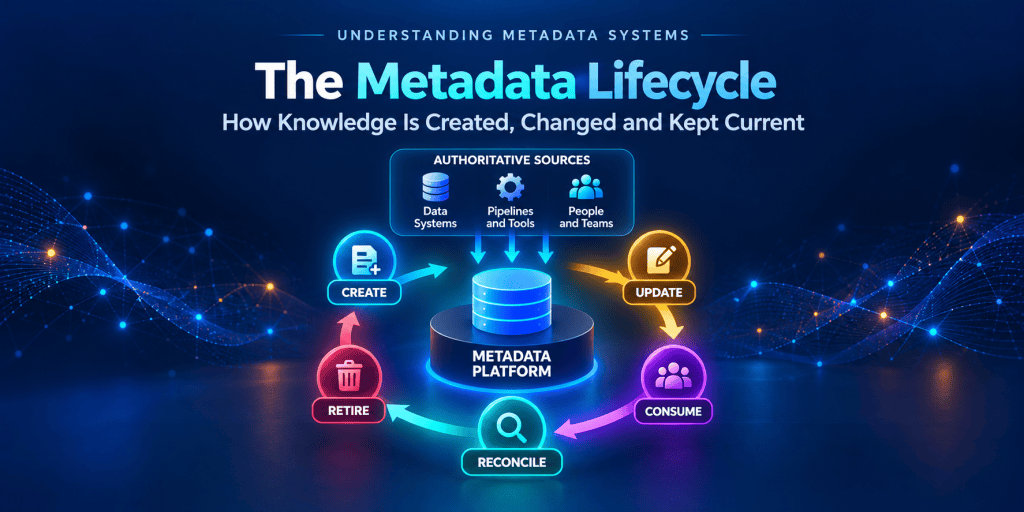
- The Metadata Lifecycle: How Knowledge Is Created, Changed and Kept Current
- From Model to Platform: How Modern Metadata Systems Represent Knowledge
- Inside a Metadata Platform: Storage, Events, Search and Distributed State
- Operating Metadata at Scale: Reliability, Consistency and Observability — Coming soon
- Metadata for AI: Giving Machines the Context to Understand and Govern Data — Coming soon


Leave a Reply